Nathan Lambert推文
中国开源模型成为AI研究默认选择
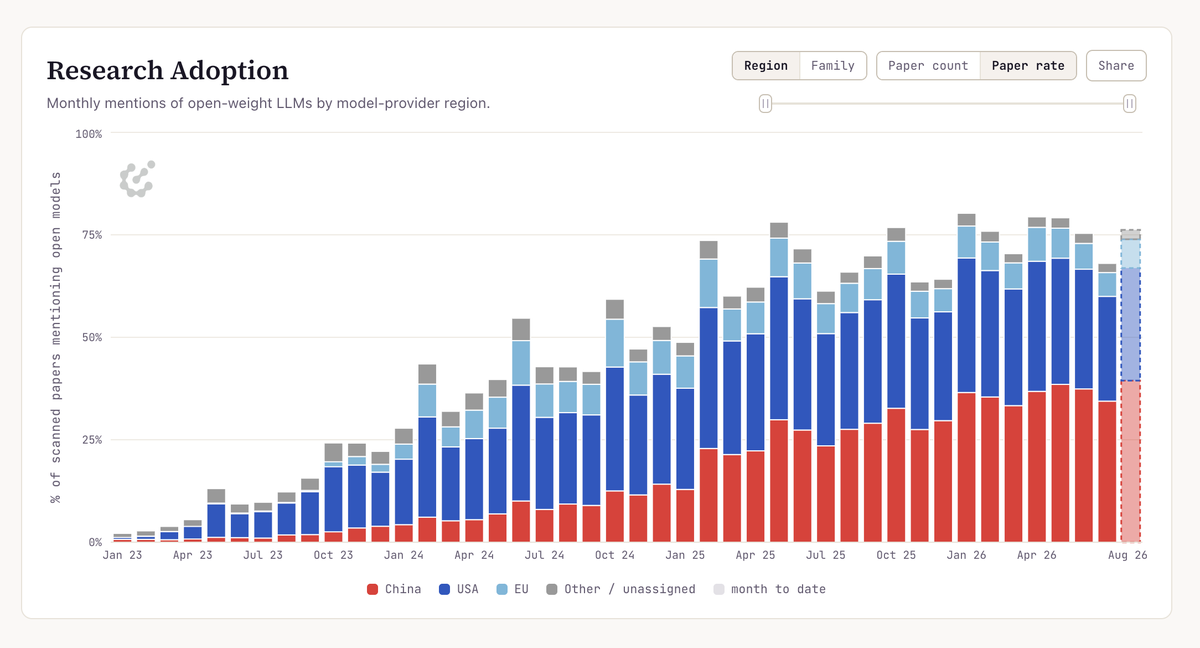
作者用Codex分析了ChatGPT以来50万篇arXiv论文,发现2024年约30%论文提及美国开源模型,10%提及中国模型;如今约40%提及中国开源LLM,美国仅25-30%。中国模型已成研究默认,提及率仍在增长,而美国开源模型停滞。Qwen稳定增长,Llama在2025年4月达峰后下滑,DeepSeek在R1后明显跃升。
译文
上周末,我让 Codex 解析了自 ChatGPT 问世以来的 50 万篇 arXiv AI/ML 论文,以了解哪些开放模型被用于研究。2024 年,约 30% 的论文提到美国开放模型,只有 10% 提到中国模型。如今,约 40% 的论文提到中国(开放)大语言模型,而提到美国模型的只有 25-30%。中国模型已成为研究默认选择。中国模型的提及率仍在增长,而美国开放模型则停滞不前。在查看这些数据时,需要记住论文的发表相对于模型发布有明显滞后,因为研究需要很长时间。Qwen 的稳步增长反映了这一点,Llama 的持久影响力也是如此。其他一些观察:1. Qwen 一直在稳步增长,如今提及任何大语言模型的论文中,有三分之一会提到 Qwen。OpenAI 的闭源模型总体占比最高,约为 37%。2. Llama 在 2025 年 4 月左右达到峰值,占提及任何大语言模型(包括 ChatGPT 等)论文的 30%。Llama 4 大约在同一时间发布,此后 Llama 的提及率一直在下降。3. Gemini 和 Claude 的提及率低于领先的开放模型,出现在 10-15% 的论文中,落后于 Qwen、Llama 和 DeepSeek。开放模型应当且确实构成了开放研究的基石。提及任何大语言模型的论文比例自 2023 年以来持续攀升。 | 年份 | 一月 | 四月 | 七月 | 十月 | |------|------|------|------|------| | 2023 | 10.43% | 15.39% | 18.69% | 32.18% | | 2024 | 29.70% | 33.93% | 35.70% | 44.25% | | 2025 | 39.23% | 45.28% | 44.94% | 53.52% | | 2026 | 55.49% | 57.26% | 53.14% | 待定 | 如今超过 50% 的 AI 论文提及大语言模型,而 2023 年这一比例仅为 10%。其他说明:- Gemma 和 Mistral 的提及率在 5-10% 左右徘徊。- 我们钟爱的完全开放 Olmo 模型自 2024 年 1 月首次发布以来,提及率一直约为 1%。- DeepSeek 在 2025 年 1 月 R1 发布后出现了明显的跃升。- 数据来源于最热门的 ML arXiv 分类:cs.AI、cs.CL、cs.CV、cs.LG、stat.ML。与我们的下载量和衍生模型数据一样,这些数据在 Interconnects 开放模型仪表板上每日更新。
Over the weekend I had Codex parse 500K arXiv AI/ML papers since ChatGPT to understand which open models are used for research. In 2024, ~30% of papers mentioned an American open model and only 10% a Chinese model. Today, ~40% of papers mention a Chinese (open) LLM, and only 25-30% an American one. Chinese models are the default for research. Chinese mentions are still growing while American open models are stagnating. When looking at this data it's important to remember that papers substantially lag model releases, as research takes a long time. Qwen's steady growth is reflective of this, but so is Llama's lasting power. Some more observations: 1. Qwen has been steadily growing, and today 1/3 of papers which mention any LLM mention qwen. OpenAI's closed models are the highest overall, at ~37%. 2. Llama peaked around April of 2025 at 30% of papers which mention any LLM (including ChatGPT etc). Llama 4 was released at about the same time, and Llama has been declining since. 3. Gemini and Claude are less common than the leading open models, mentioned in 10-15% of papers puts them behind all of Qwen, Llama, and DeepSeek. Open models should be and are the foundations of open research. The % of papers mentioning any LLM have been steadily climbing since 2023. | Year | January | April | July | October | | 2023 | 10.43% | 15.39% | 18.69% | 32.18% | | 2024 | 29.70% | 33.93% | 35.70% | 44.25% | | 2025 | 39.23% | 45.28% | 44.94% | 53.52% | | 2026 | 55.49% | 57.26% | 53.14% | TBD Now over 50% of AI papers, from 10% in 2023. Other notes: - Gemma and Mistral hover around 5-10%. - Our beloved fully-open Olmo models have been ~1% since the first release in Jan. 2024. - DeepSeek has a clear jump after R1 in Jan. 2025 - Data derived from the most popular ML arXiv categories: cs. AI, cs. CL, cs. CV, cs. LG, stat. ML Just like our downloads and derivative model data, this is updated daily on the Interconnects Open Model Dashboard.